WebbyLabCasesObservability, Business Monitoring and AI Agent Access for an Electronics Retailer
Observability & Business Monitoring
Monitoring for Brain's e-commerce platform: business metrics, alerts within minutes and read-only AI agent access
CLIENT
Brain - Ukrainian retailer of computers and electronics
Industry
E-commerce, Retail, Observability, AI
Services provided
Solution Architecture
DevOps & Infrastructure
Observability & Monitoring
Business Metrics & Alerting
Security & Access Management
AI Agent Integration (MCP)
Application Support & Maintenance
Services provided
Solution Architecture
DevOps & Infrastructure
Observability & Monitoring
Business Metrics & Alerting
Security & Access Management
AI Agent Integration (MCP)
Application Support & Maintenance
The Brief
Brain is a Ukrainian retailer of computers and electronics with an online store and a large product catalogue. WebbyLab has worked with Brain before on its B2B portal for dealers. The platform runs on four cloud servers: three web servers (the main portal, marketing and the cataloguer) and a production MySQL database with Elasticsearch. Orders move from checkout to payment through several providers and are exported to the company’s ERP.
Production ran without metrics, central logs or alerts. For an e-commerce business that means lost orders go unnoticed, so Brain asked WebbyLab to make it visible: one place for servers, application and business processes, alerts that reach the right person, and no new risks for production.
Challenge
No metrics, no central logs and no alerts: problems were reported by customers, the ERP team and colleagues, usually after the fact and without details
Simple questions took half an hour: finding the most CPU-hungry endpoint meant SSH into three servers, parsing logs by hand and merging the results
Silent failures: when a bank declined a payment, the order was never exported to the ERP, with no error, no log line and no alert
Failures lasted weeks: customer notifications sat in a queue for almost three weeks, and a nightly job failed every night unnoticed
Capacity decisions were guesswork, with no way to tell customer load from bot traffic
Monitoring had to add no inbound ports, read the production database safely and stay far below SaaS monitoring prices
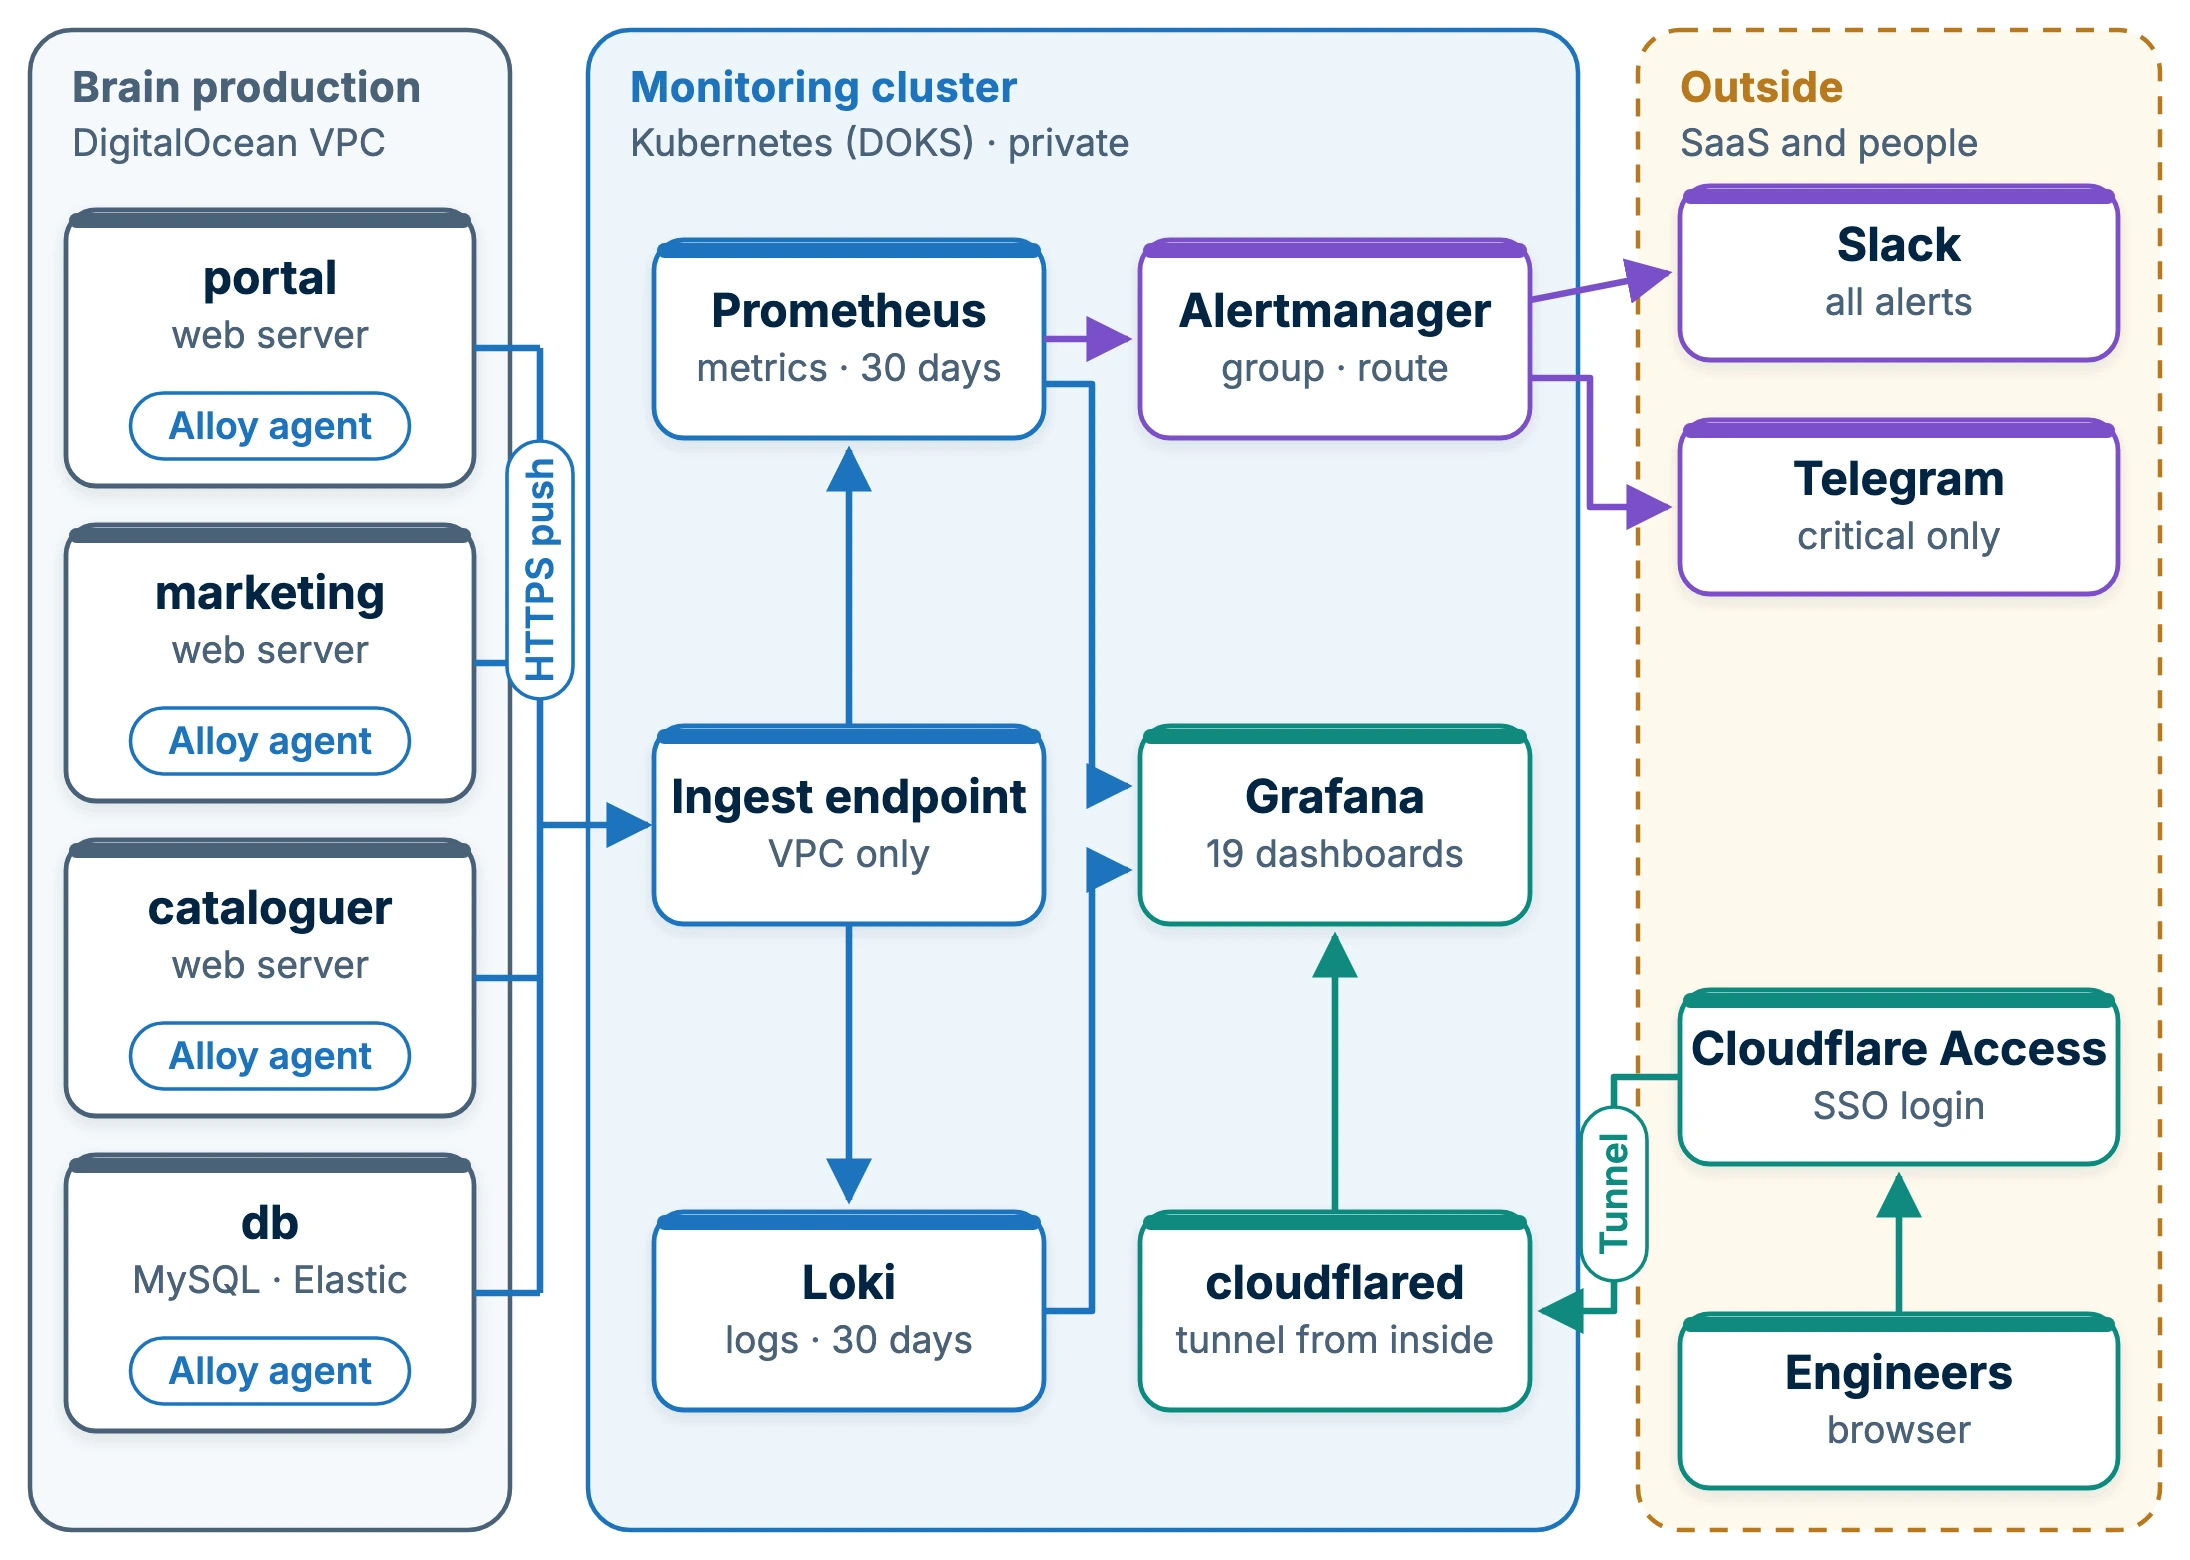
One place for every signal: servers send data to a private monitoring cluster; people and alerts reach it from outside.
Solution Overview
WebbyLab’s DevOps team built a monitoring stack in four layers (infrastructure, application, business and alerting), added zero-trust access for people and opened the same data to AI agents in read-only mode. Everything is described as code in git: Helm, Ansible, reviewed changes and SOPS-encrypted secrets.
Data collection without new open ports
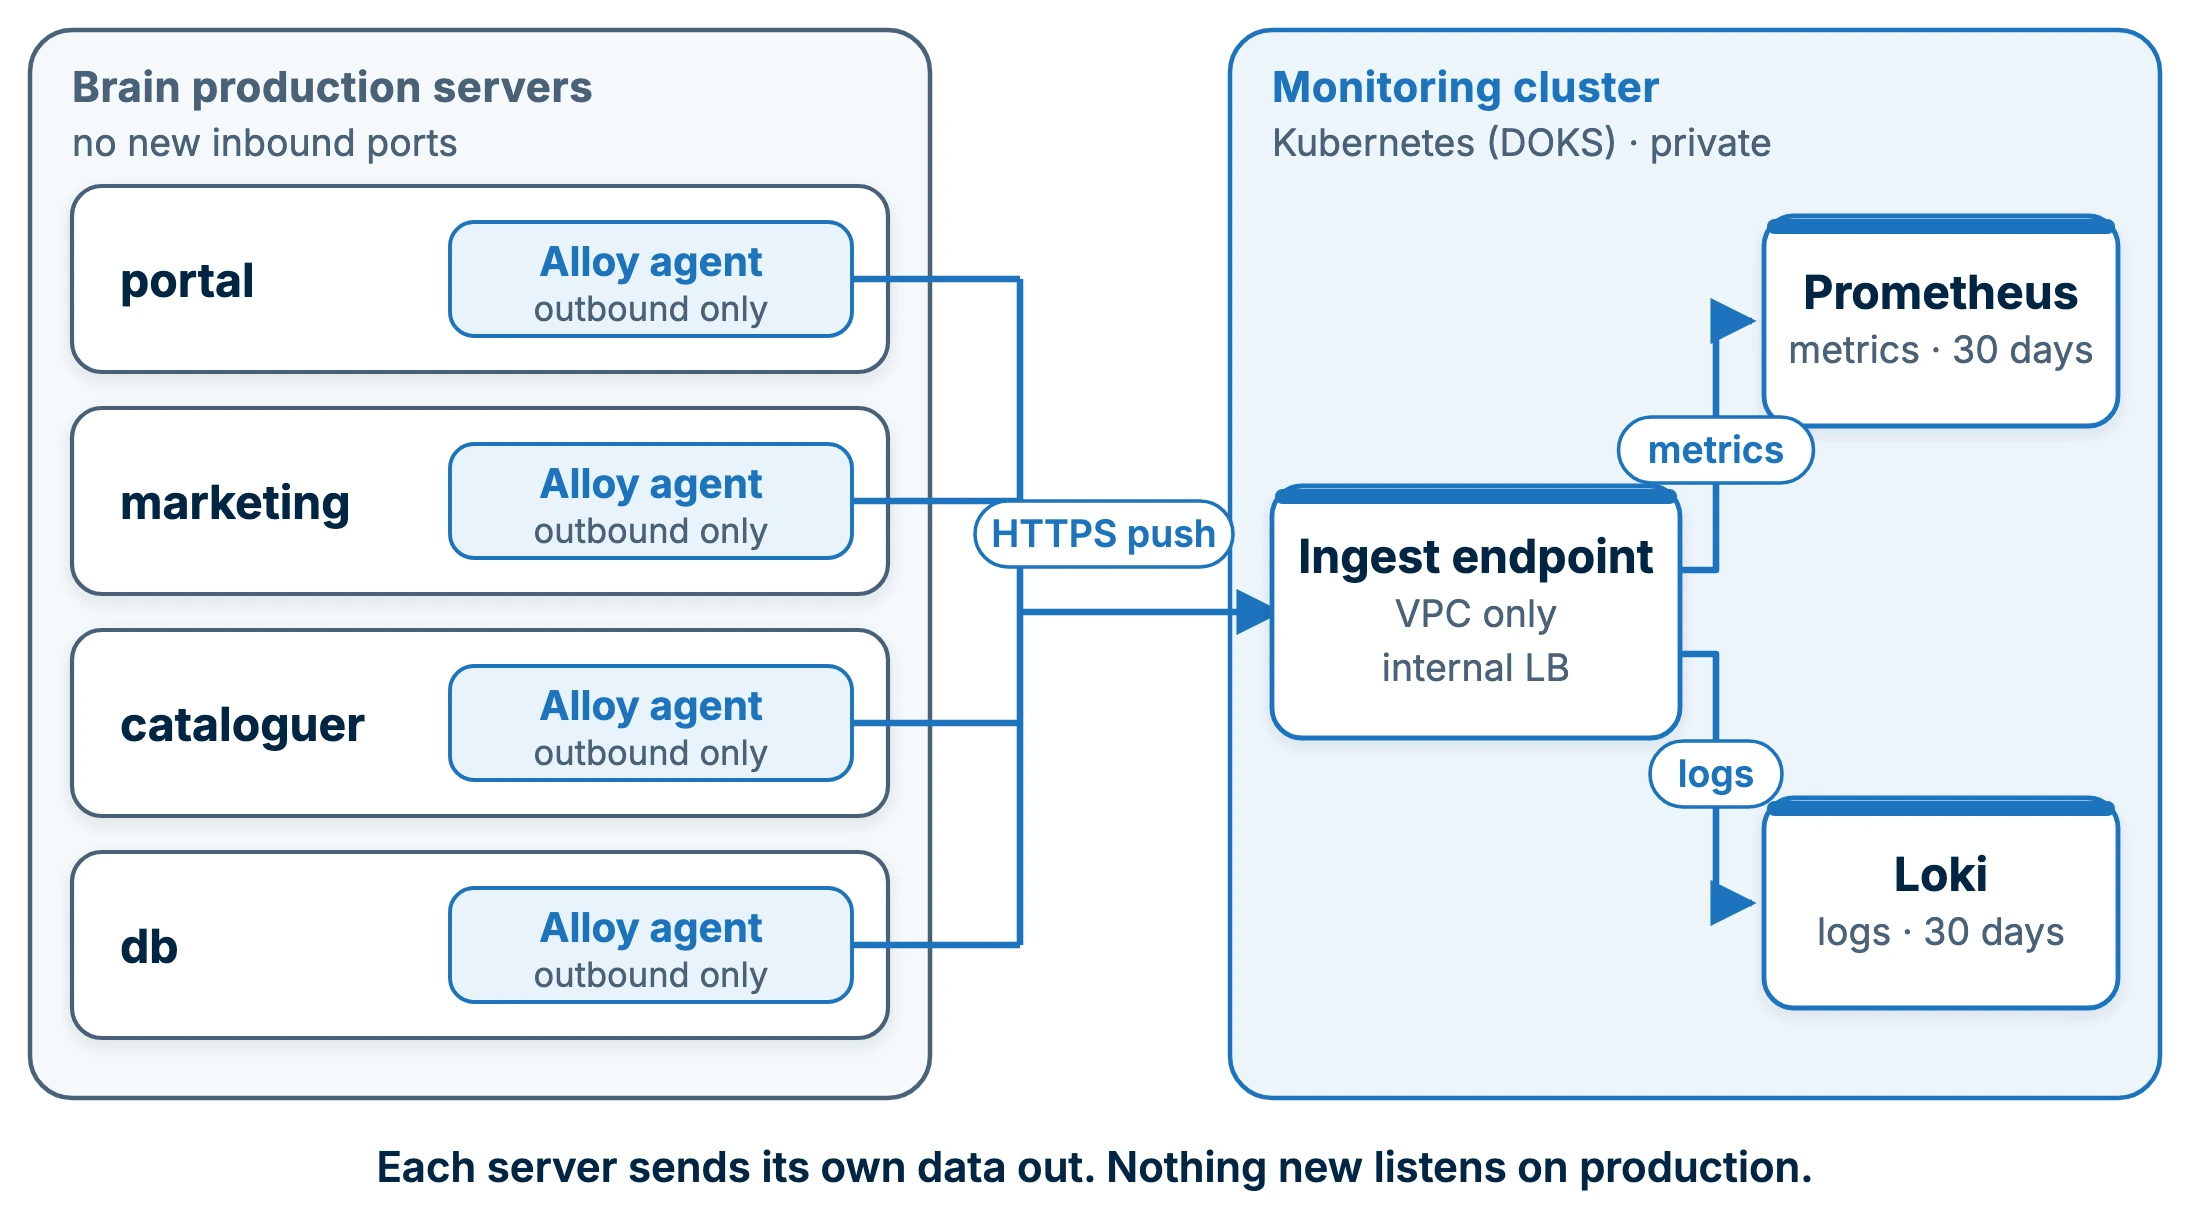
A dedicated Kubernetes cluster (DigitalOcean DOKS) in Brain’s private network runs Prometheus (metrics, 30 days), Loki (logs, 30 days), Alertmanager and Grafana. A Grafana Alloy agent on each server reads existing metrics, logs and local exporters and pushes them out over HTTPS. Nothing new listens on production.
Each server sends its own data out; nothing new is open on production.
CPU and latency per endpoint
One response header naming the route, plus cron exit codes, were the only changes to Brain’s code. Alloy turns php-fpm and nginx logs into per-route CPU and latency metrics; nginx, PHP-FPM, memcached, MySQL, Elasticsearch, CPU, memory and disks are collected every 15 seconds. Five linked Grafana panels lead from symptom to cause.
Business metrics from the production database
A SQL exporter reads orders, payments by provider, ERP exchange, SMS and notifications, the catalogue and price feeds every minute. Every query was measured on production first; one 88-second query was rewritten. Guardrails: a SELECT-only user, a connection cap, a local socket, query time limits and a fixed schedule.
Alerting that reaches the right person
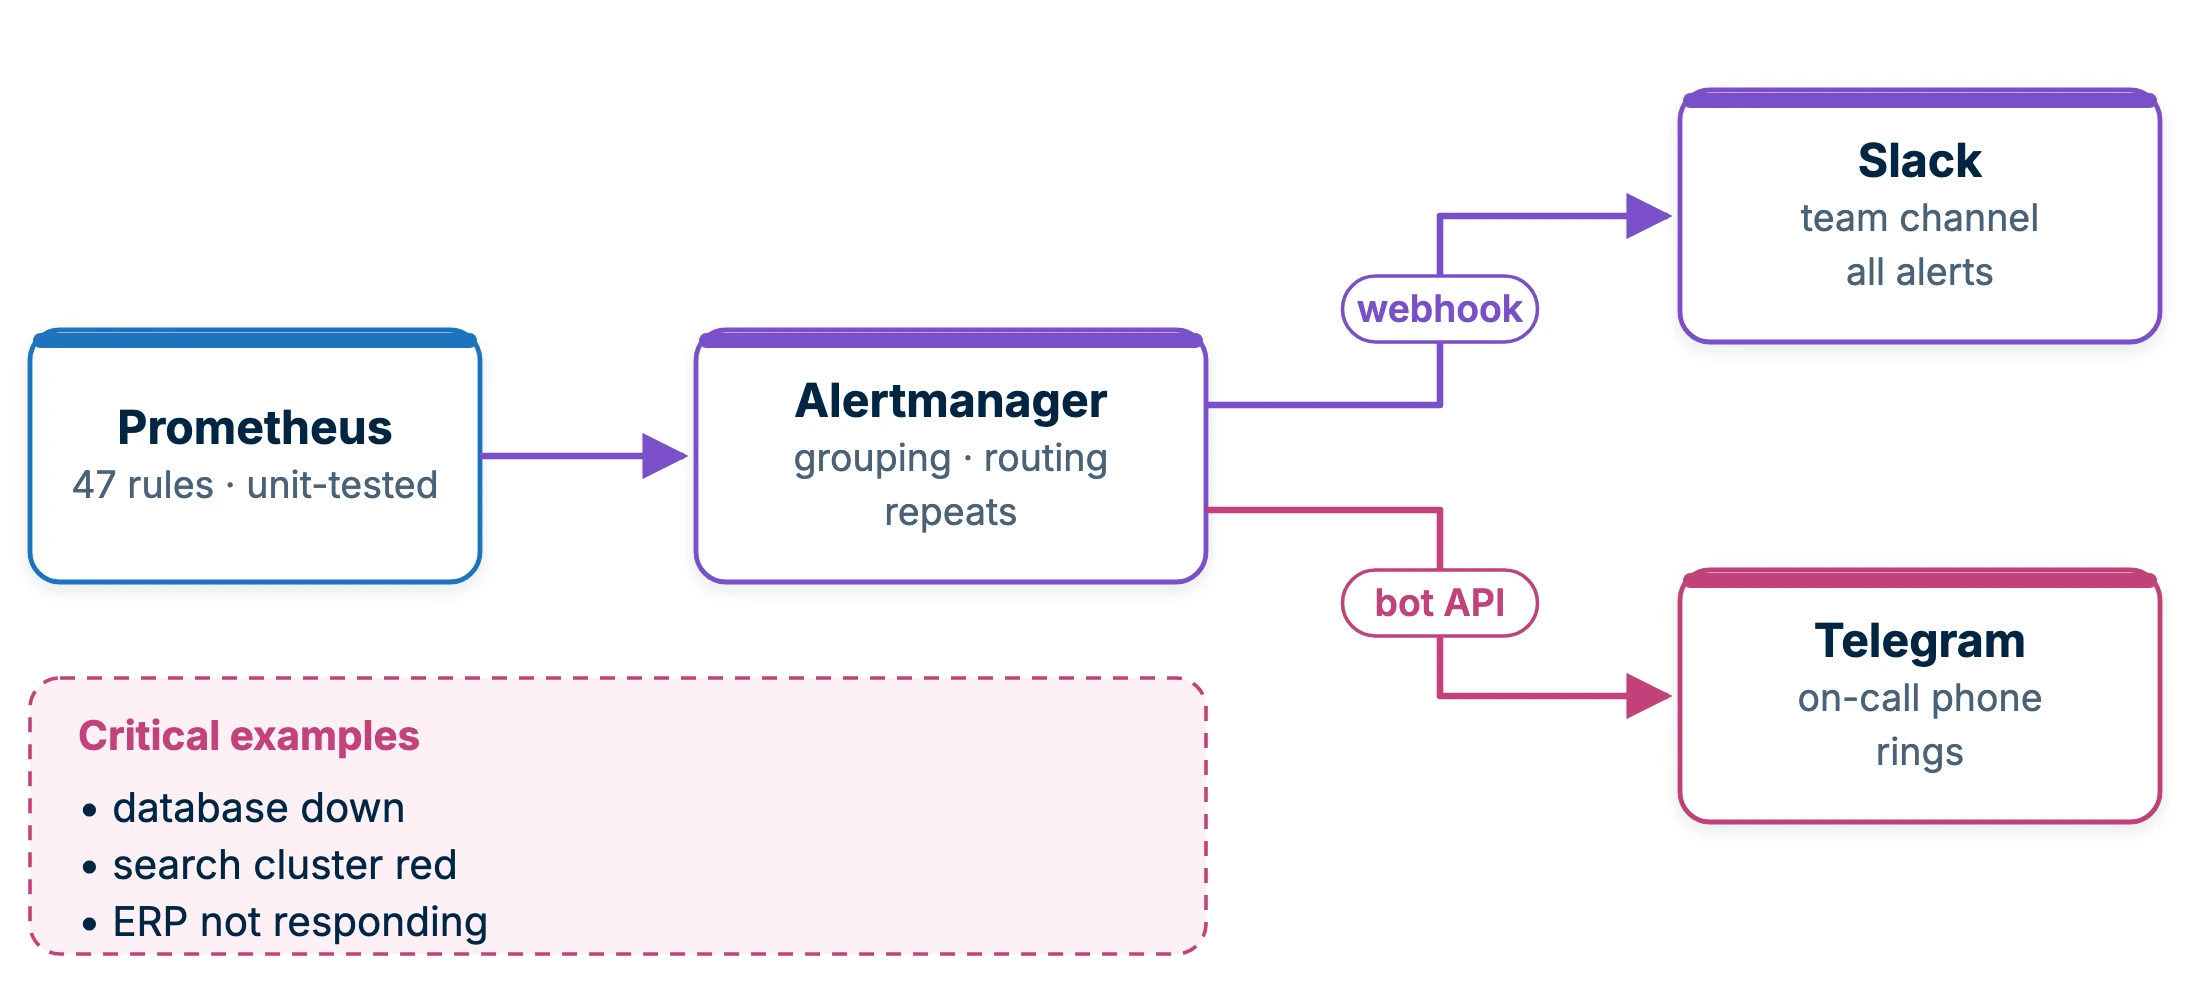
47 alert rules, grouped and routed by Alertmanager. Every alert goes to Slack; critical ones (database down, search cluster red, ERP not responding) also ring a phone in Telegram. All rules are unit-tested before deployment, with 85 tests for business rules alone.
Every alert goes to Slack; the critical ones also ring a phone in Telegram.
Zero-trust access to dashboards
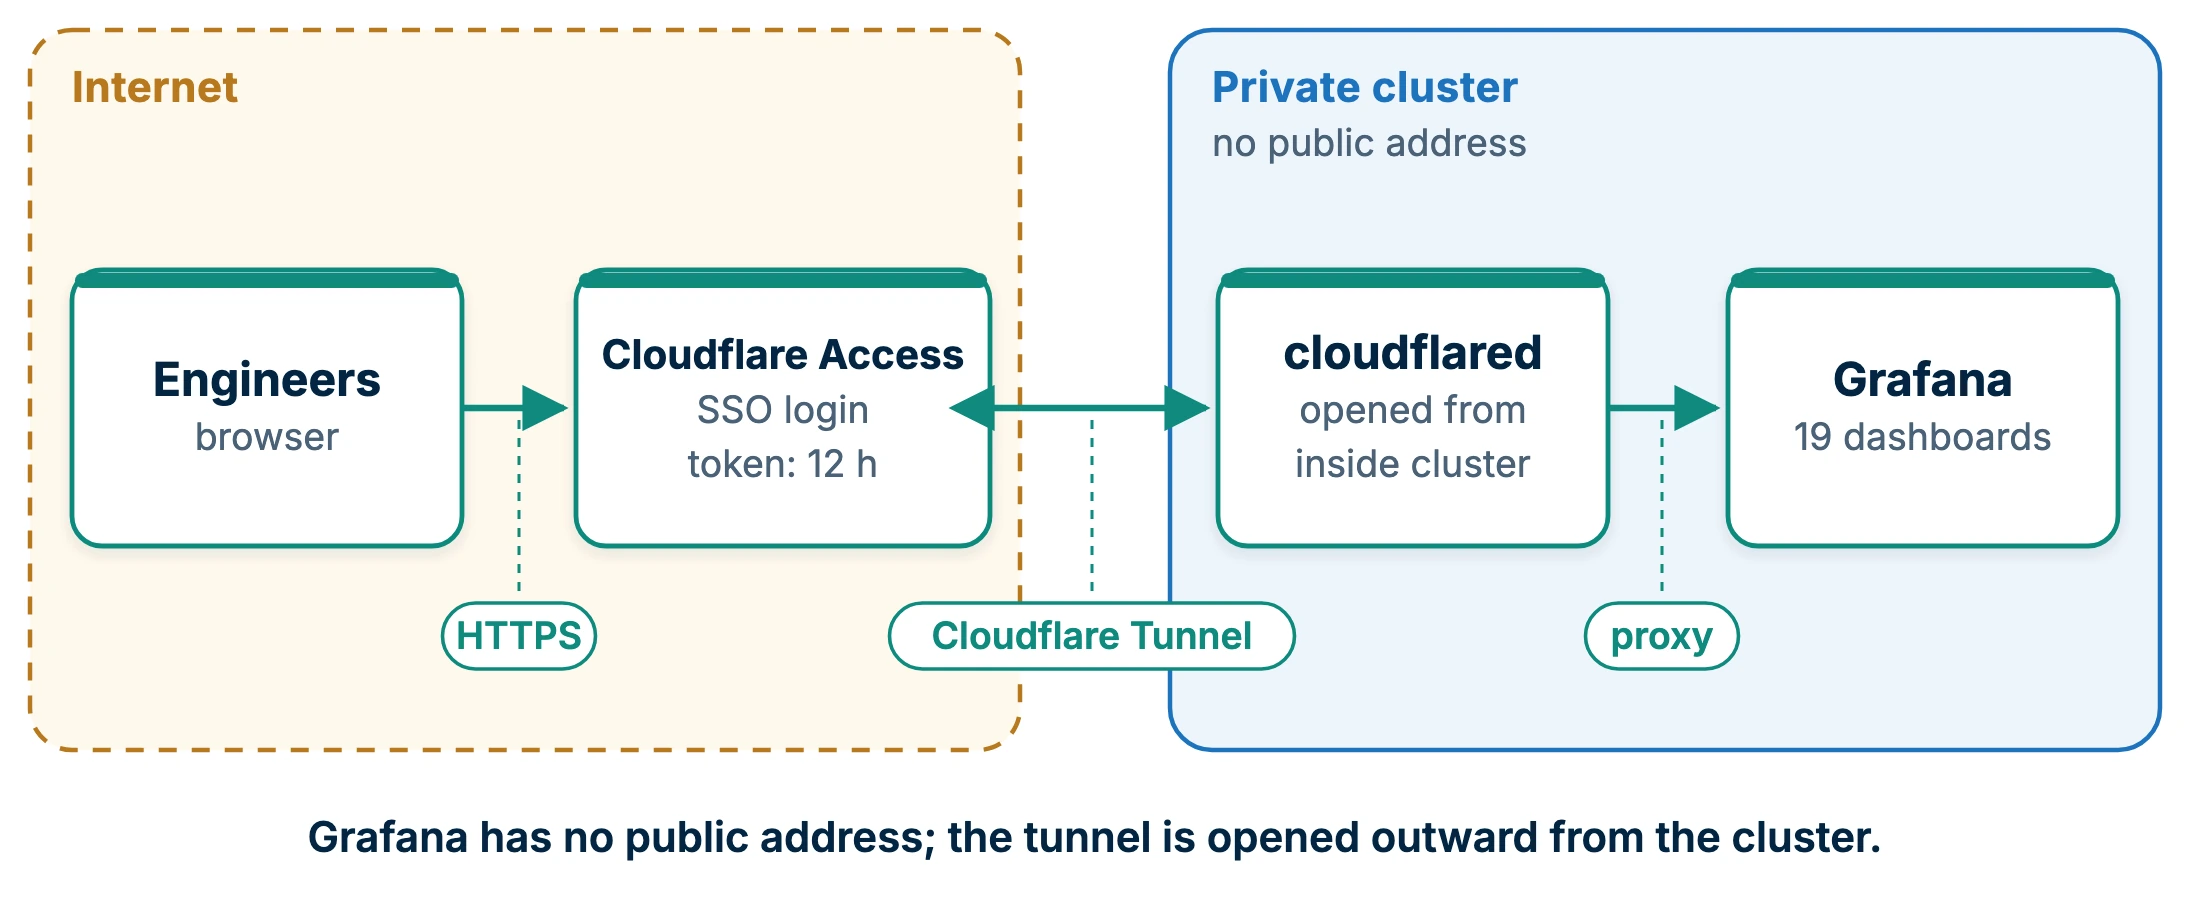
Grafana (19 dashboards) has no public address. Engineers sign in through Cloudflare Access, and a Cloudflare Tunnel opened from inside the cluster carries the traffic. Personal tokens live 12 hours.
Engineers sign in through Cloudflare Access; Grafana has no public address.
AI agent access, read-only
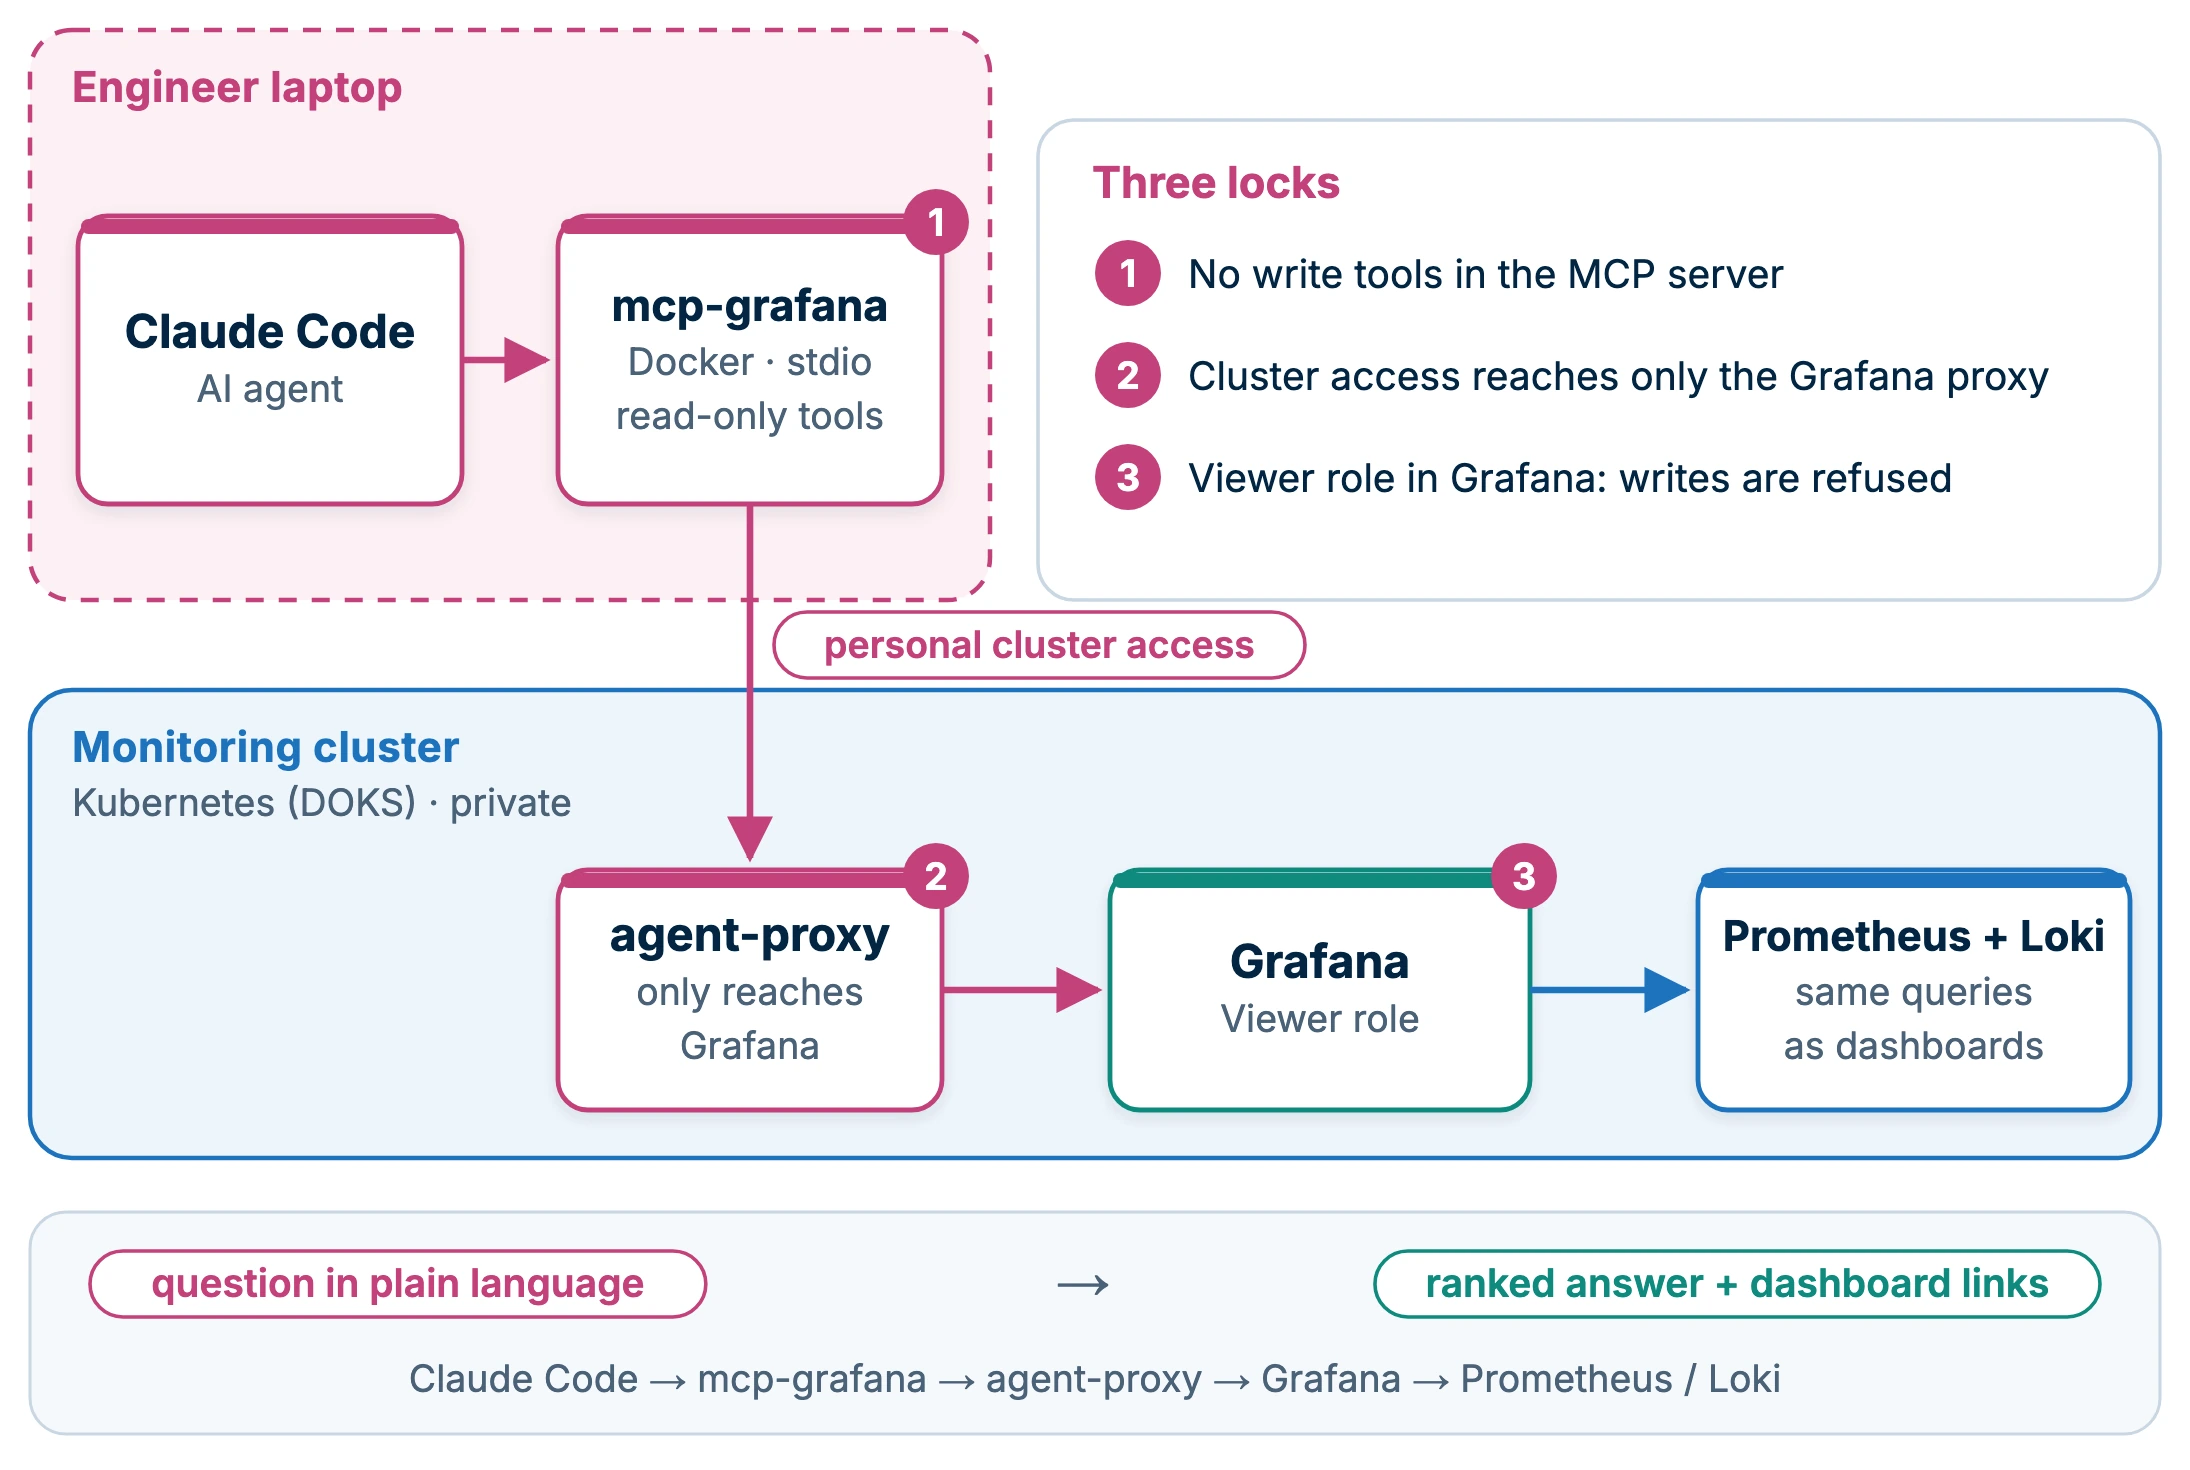
Engineers ask Claude Code questions in plain language, the same approach WebbyLab uses in AI agent development. Through the Grafana MCP server, the agent runs the same Prometheus and Loki queries the dashboards use and answers with a ranked result and dashboard links. Three locks keep it read-only: no write tools, personal cluster access limited to the Grafana proxy, and a Viewer role in Grafana. Write attempts are refused.
The AI agent reads the same data through a personal, read-only door.
Key Outcomes & Value Delivered
5 silent failures found in 48 hours: orders dropped after declined payments (~90 a month), 12 notifications stuck since September, a stalled reviews feed, a nightly job failing every night and delayed SMS.
Time to detect: weeks to minutes: critical problems now ring a phone within 2–30 minutes, before a customer writes in.
Monitoring at a fraction of SaaS cost: about $85 a month versus an estimated $545–770 for a SaaS such as Datadog at the same volume, saving $5.5–8k a year while data stays in Brain’s own network.
Declined payments become sales again: once the fix ships, every order a bank declines reaches a sales manager, who can offer another payment method.
Release outage fixed the same evening: a release that took the site down for three minutes was diagnosed within minutes and fixed 39 minutes later.
SMS and ERP outages ring a phone: a five-hour SMS outage that cut completed checkouts to 67% would now raise an alert in about ten minutes; the ERP alert caught 3 of 3 real outages on 30 days of history, with no false alarms.
Fresh catalogue every morning: the nightly catalogue update dropped from 50–55 minutes to 6 and no longer freezes its server.
Hardware bought on data: a capacity warning arrives weeks ahead, and the team sees whether load comes from customers or bots before paying for a bigger server.
Answers in seconds: a question that took half an hour across three servers is now one Grafana panel, or one plain-language question to the AI agent.
WebbyLab Expertise Demonstrated
Observability architecture: metrics, logs and business data in one private, cost-efficient stack
Business monitoring: orders, payments and ERP exchange turned into metrics and alerts on a live production database
Security by design: no inbound ports, zero-trust access, least-privilege database and agent access
Reliable alerting: routed, deduplicated, unit-tested rules, back-tested on history
AI agent integration: read-only MCP access for plain-language questions about production
Infrastructure as code: everything in git, reviewed and reproducible
Technologies
Prometheus
Loki
Grafana (19 dashboards)
Alertmanager + promtool tests
Grafana Alloy
sql_exporter
Kubernetes (DigitalOcean DOKS)
Helm, Ansible, SOPS
Cloudflare Access + Tunnel
Slack, Telegram
Claude Code + Grafana MCP (read-only)
Launching a new project or improving an existing one?
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.